Context before model
Clarify the problem, user, data, and constraints before choosing the method.
Document intelligence & OCR
We treat OCR as more than a detached extraction step. Forms, reports, drawings, and technical records should enter the decision flow with their source, confidence, version, and correction path visible; users should be able to compare extracted data with the original before it is used.
Real product view
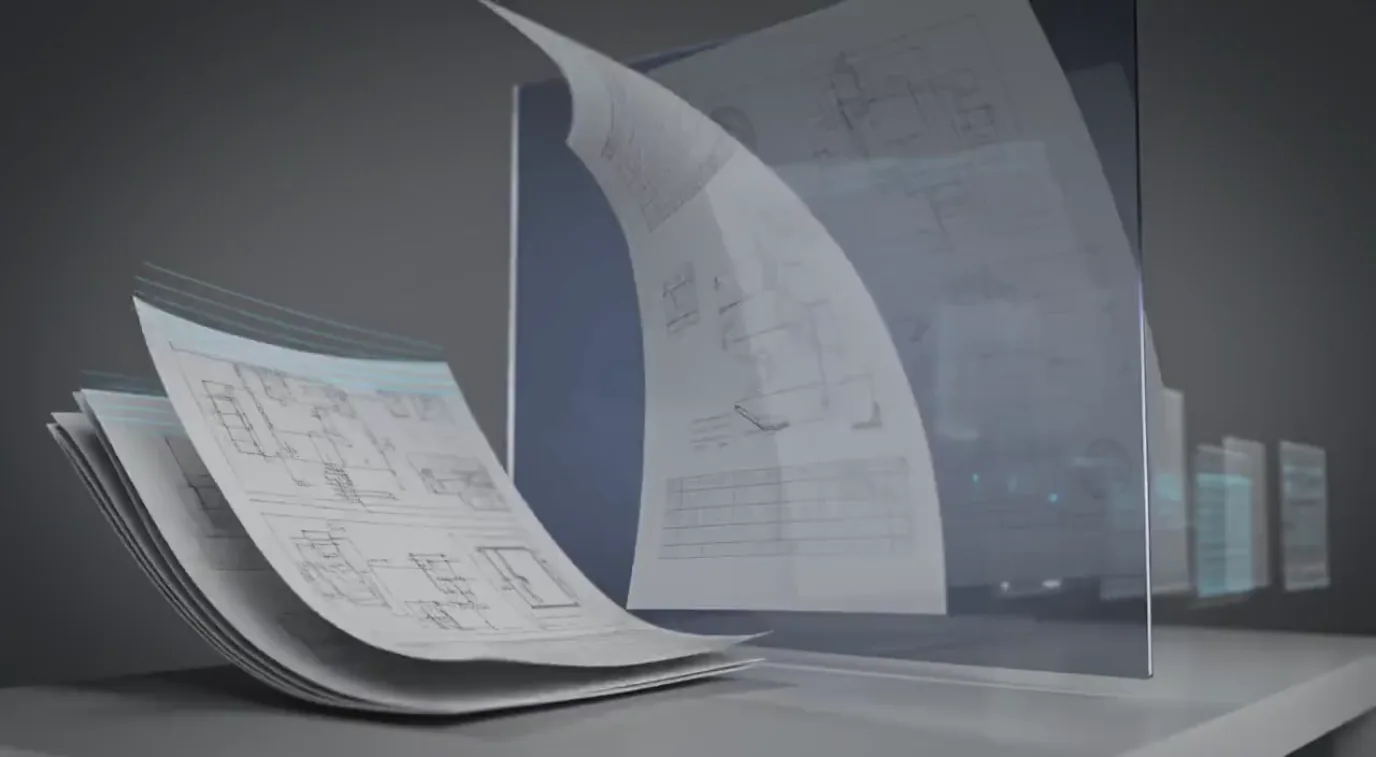
This still is taken from the supplied OCR video and shows the document, extraction, and review path in context.
Product evidence
This product view sits beside the video so OCR is understood as a reviewable work step, not decorative imagery.
Document intelligence and OCR
From forms and reports to drawings and technical records, text extraction is only the beginning. Data should be classified, validated, searchable, and visible inside the decision flow.
Monitoring and forecasting
An anomaly detector or forecast matters when a team can see what changed, why it matters, and what action is possible. We place model output beside trend, status, and user knowledge.
Decision-led design
Trust is not built by hiding complexity. Users should know where data came from, what the model says, where the limit is, and how to correct the result.
Clarify the problem, user, data, and constraints before choosing the method.
AI output should appear where the decision and action actually happen.
Every important result should be visible, reviewable, correctable, and traceable to its source.
Competitive advantages
The product value is more than text extraction; provenance, confidence, version, human correction, and the data's next use stay attached to the output.
Users can see which document and revision produced the data and which part needs review.
OCR is not an unquestionable final output; users can compare fields with the source and correct them.
Structured data with confidence and revision context can feed contextual search, reporting, or workflow.